Why Growing Companieshave to deal with

ArchitectureDebt

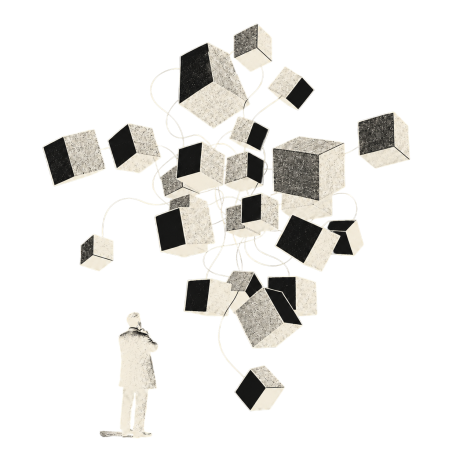
A person looking at a complex cluster of architectural blocks

The Decisions You Make in Year One Decide What You Can Do in Year Four

There is a pattern worth naming, because it repeats across companies that otherwise have very little in common.

A company builds quickly in its first year or two. The system works. Customers arrive. Then somewhere in the third or fourth year, things begin taking longer than they should. Deals sit in security review. Integrations get quoted in quarters. A second product line takes far more engineering than the first one did. Nobody can point at the cause, and the usual answers — hiring, process, focus — do not fix it.

The cause is almost always a small number of structural decisions made very early, when moving fast was the right thing to do.

The decisions in question

They are rarely dramatic. In most systems they come down to four or five choices:

  • Whether a change to a record is written over the old value, or kept as history.
  • Whether isolation between customers is built into the platform, or maintained by convention.
  • Whether access rules live in one place, or in every screen that needed them at the time.
  • Where the authoritative version of a customer, an asset or a transaction actually sits.
  • Whether an audit trail is a property of the system, or a feature on a few pages.

None of these are mistakes when they are made. They are the correct trade at the time — fewer moving parts, faster releases, and no customer yet asking the questions that would make the harder choice worth it. Speed in the early years is what buys a company its later years.

They become structural the moment everything built afterwards assumes they are true.

Why this is different from ordinary technical debt

Every engineering team carries technical debt, and every competent team knows how to retire it. A messy service, an untested path, a slow query. It sits inside a boundary. It can be scoped, funded and cleared.

This does not sit inside a boundary. It sits underneath one. When the tenancy model is wrong, or access rules are spread across fifty places, or history was never kept, the problem is not in any single module. It is in the assumption every module was built on.

It is the difference between replacing a window and moving a load-bearing wall. The first is work. The second is a different kind of project entirely, and it has to be treated as one.
The cost shows up outside engineering

This is what makes it hard to see and harder to fund.

It shows up in sales, as enterprise security reviews that take weeks longer than they should, because the answers have to be assembled by hand.

It shows up in product, when a second line of business needs the same customer record and there is no clean way to share it.

It shows up in partnerships, when an integration asks for a history the system never recorded.

And it shows up as a general slowness that everyone feels and nobody can name. By the time it is discussed at leadership level, it is usually described as an execution problem, which sends the organisation looking in the wrong place.

AI makes it visible sooner

Most AI initiatives that stall inside established companies are not failing on model quality. They are failing on records.

Anything useful built on top of operations has to establish three things: which record is authoritative, who was permitted to see it, and what happened in what sequence. A system that overwrote its history cannot produce that history later. No model compensates for a record that was never kept.

The failure mode is quiet, which is what makes it worth naming. It is a confident answer drawn from the wrong version of the truth, or from a record the person asking should never have been able to reach.

Five questions worth asking

This takes an afternoon, and it is more revealing than most formal architecture reviews.

  • For any record, can you establish who changed it, when, and under whose authority, without reading application logs?
  • If your access rules changed tomorrow, how many places would have to be edited?
  • Can you stand up an isolated customer environment without branching the code?
  • Could a third party read your full data model from a documented export, without your team explaining it?
  • To answer one operational question end to end, how many systems must be consulted, and who decides which of them is right?

Three uncomfortable answers means this is structural, not backlog. The distinction matters, because the two are funded, sequenced and staffed differently.

Why the rewrite usually fails

The instinct at this point is to start clean. It is an honest instinct and it rarely works.

A full rebuild asks the business to fund two years with little visible change while competitors keep shipping. It draws on the same engineers holding the existing system together. And it reproduces the conditions that created the problem originally: deadline pressure, incomplete requirements, and structural decisions made once, under load, then inherited for a decade.

The approach that holds up is less satisfying to describe. Build the foundation first — identity, tenancy, access, workflow, audit, history — as shared services the whole business stands on rather than something each application implements its own way. Then move capability onto it one area at a time, keeping the existing path running until the new one has earned trust.

It is slower to announce and considerably faster to finish.

How WayBeyond.tech builds

We work in the opposite order from most teams: the foundation exists before the application does.

Our Enabler framework carries that structural layer already built and already proven — multi-tenancy, access control, workflow, scheduling, audit, encryption. Applications are generated on top of it. The decisions that ordinarily get made under deadline pressure in the first few months arrive already made, made once, and made the same way across every module.

Two consequences matter more in a board meeting than in a stand-up. The system we hand over is a documented codebase the client owns outright and can maintain with any competent engineering team, along with their data. And because the foundation is not rebuilt from scratch each time, work that conventionally takes around two years has been delivered in eight to ten months.

The question that changes

In the first year, moving fast is correct, and companies that hesitate rarely get a fourth year to worry about.

By the third year the question quietly changes. It stops being how quickly can we ship, and becomes what has this system already decided on our behalf.

The companies that scale cleanly are not the ones that avoided this. They are the ones that looked at it early, while it was still inexpensive to change.

Share this read

Sign up to our Newsletter for all latest updates.

The AI everyone wants.
The foundation almost no one has.

Connect with us →
Write to us at:
Call us: